
Note:
Before someone starts screaming about the 1M context window in Opus 4.6, it is only available via the API with the beta flag.
Also, this is under max usage tier.
And and beyond 200k context, rates are more expensive :)
Plus, the pricing is pretty much the same as Opus 4.5.

Okay, next up:
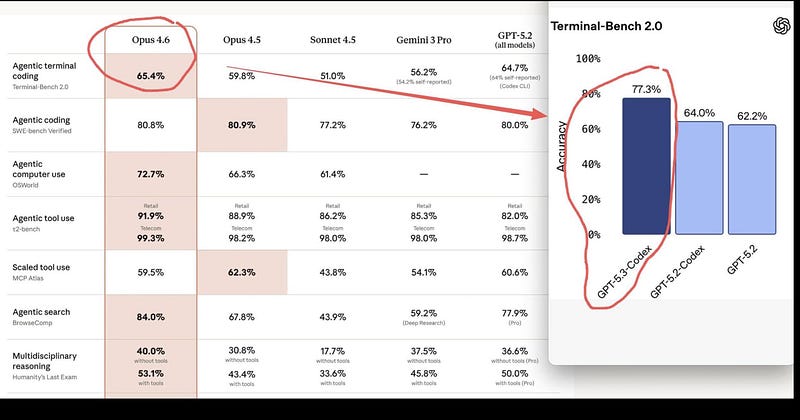
On paper, Codex 5.3 looks a lot better than the Opus 4.6.
Now, I tried using both on one of my projects.
Both performed equally well on my codebase, in my opinion.
I just did analysis on a super big feature.
Codex took more time, hallucinated less.
Opus was sufficiently faster, but hallucinated a little.
Some interesting pointers:
- For arc agi 2, OpenAI didn’t post their results at all, while Opus 4.6 literally doubled.
- GPT‑5.3‑Codex was the first model that was instrumental in creating itself. The Codex team used early versions to debug its own training, manage its own deployment, and diagnose test results.
- A bit of cat and mouse over who’d drop first and this came at a 15 minutes difference lol
I am also kinda excited about Gemini 3.5 pro max now :)
Anyway, let me develop my feature E2E and let y’all know what it looks like with either.
In case we are meeting for the first time, come over here, it’ll be worth the roller coaster of articles that are gonna come up in the next few weeks.